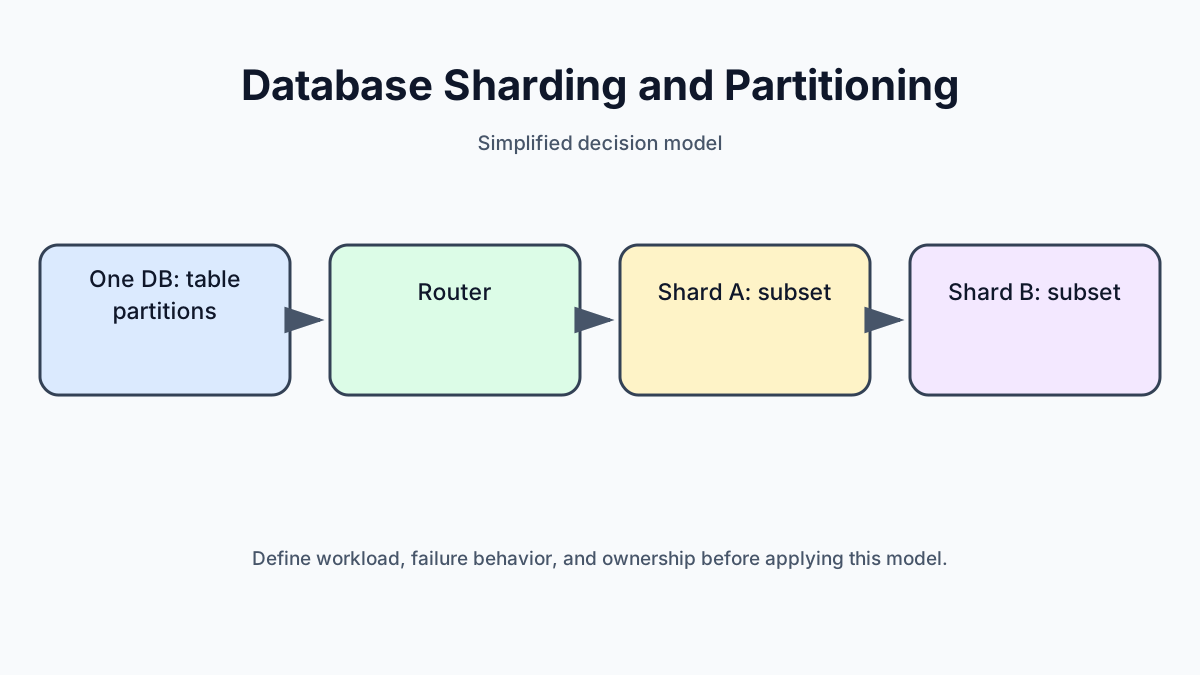
Partitioning and sharding both divide data, but they solve different classes of problem. PostgreSQL table partitioning divides one logical table into child tables managed within a database. Sharding distributes subsets of data across separate database nodes and adds a routing problem.
Confusing the two leads to premature complexity. A partitioned table does not automatically provide more write nodes, and a sharded system does not automatically make an inefficient query fast.
Diagnose the constraint first
Before changing data placement, identify what is actually constrained:
- Does a query read too many rows because its predicates or indexes are ineffective?
- Is maintenance on one very large table difficult?
- Are old data ranges deleted or archived regularly?
- Is one database host limited by CPU, memory, storage throughput, connection count, or write capacity?
- Is the workload skewed around a few tenants or keys?
- Does the availability requirement exceed the current topology’s recovery design?
Query plans, wait events, lock behavior, table and index size, write amplification, connection pressure, and workload distribution provide better evidence than total row count alone. Fixing query shape, using the right index, batching work, archiving data, or scaling the database may postpone or remove the need for data distribution.
Mastering Database Indexes is a useful starting point when the bottleneck is access path rather than node capacity.
PostgreSQL partitioning stays inside the database
Declarative partitioning lets PostgreSQL treat several physical tables as one logical partitioned table. Rows are directed to partitions according to a partition key and strategy.
Range partitioning assigns non-overlapping ranges, commonly time intervals or ordered identifiers. It can fit time-oriented data where queries and retention align with the same range.
List partitioning assigns discrete values to partitions. It may fit categories, regions, or a bounded set of tenant groups when the mapping is intentional.
Hash partitioning assigns rows using a hash remainder. It can spread rows without natural ranges, though it does not make unrelated queries target one partition unless their predicates include the partition key.
All of these can remain on one PostgreSQL server and share its CPU, memory, storage, connection, transaction, and recovery boundaries. Partitioning changes organization and planning opportunities; it is not horizontal database scaling by itself.
What partitioning can improve
Partition pruning can avoid scanning partitions that cannot satisfy a query. It is most useful when query predicates align with the partition key and PostgreSQL can prove which partitions are irrelevant. A query that lacks that predicate may still inspect many partitions.
Partitioning can simplify lifecycle operations. Detaching or dropping an old time partition can be operationally cleaner than deleting a large number of rows individually. Loading or validating data by partition can also support controlled maintenance.
Indexes are generally created and maintained per partition under the partitioned structure. This can make individual indexes smaller and maintenance more targeted, but it also increases the number of objects. Schema changes, statistics, autovacuum behavior, and operational tooling must account for every partition.
Too many partitions can increase planning and management overhead. Partitioning should follow meaningful access and lifecycle boundaries, not create tiny tables merely because the feature exists.
Constraints still need careful design
Uniqueness across a partitioned table has restrictions tied to the partition key because separate partition indexes cannot freely enforce every global uniqueness rule. Foreign keys, updates that move rows between partitions, default partitions, and attach/detach operations all deserve version-specific validation.
Choose the partition key based on dominant query and data-lifecycle behavior. A timestamp key helps time-window pruning and retention, but it may not help tenant-specific queries that span time. A tenant key can isolate tenant ranges but may create uneven partitions when tenant sizes differ.
Partitioning also does not eliminate hotspots. The newest time partition can receive nearly all writes. All partitions can still contend for the same storage or WAL path. Measure after partitioning rather than assuming divided tables mean divided load.
Sharding distributes ownership
Sharding places different data subsets on separate database nodes. An application, proxy, or database platform must determine which shard owns a key and route the operation there.
This can distribute storage and workload beyond one node, but it changes application and operational semantics:
- cross-shard queries require fan-out and result merging;
- multi-shard transactions need coordination or redesigned boundaries;
- global uniqueness is harder to enforce;
- schema migrations must reach every shard safely;
- backups and restoration must produce a coherent system state;
- node failure creates partial rather than necessarily total unavailability;
- adding capacity requires moving data and updating routing.
These costs remain after the original capacity event passes. Sharding is therefore a durable architecture decision, not a routine optimization.
Choose a placement strategy
Range sharding assigns ordered key ranges to nodes. It supports targeted range access and understandable movement, but sequential or time-based keys can concentrate new writes on one shard. Unequal customer sizes can also create skew.
Hash sharding derives placement from a hash. It often spreads identifiers more evenly, but range queries may fan out. Simple modulo by the current shard count remaps many keys when that count changes; production designs need a deliberate movement strategy such as virtual buckets or another stable indirection.
Directory sharding stores a mapping from entity or tenant to shard. It supports explicit placement and moving one tenant independently, but the directory becomes critical routing state that must be available, consistent, and cached carefully.
Evenly distributed row counts do not imply evenly distributed load. One tenant can generate far more queries, writes, or expensive operations than another. Model request cost and growth, not only keys.
Align shard keys with transaction boundaries
The best shard key keeps common transactions and queries on one shard. In a tenant-oriented system, tenant identity may provide that boundary if tenant data and operations are sufficiently independent. In another domain, account, region, or aggregate identity may be more appropriate.
Ask what must remain atomic. A transaction that updates two entities on different shards either needs distributed coordination or a redesigned asynchronous workflow with compensation and explicit intermediate states. Both are more complex than a local PostgreSQL transaction.
References across shards cannot rely on ordinary local foreign keys. The application may need validation, replicated reference data, or looser consistency. Reporting across all shards requires a fan-out service, replica pipeline, or analytical store with defined freshness.
The distributed-state consequences are explored further in Session State in Distributed Applications.
Plan rebalancing before the first split
Capacity will not remain evenly distributed. Define how a shard is split, how data is copied, how concurrent writes are captured, when routing changes, and how the old copy is retired. Every step needs rollback or reconciliation.
Online movement commonly needs a snapshot plus change capture, dual reads or writes under controlled conditions, validation, and a cutover. Dual writing without a consistency protocol can create divergent copies. A routing cache can continue sending work to the old owner after cutover unless versions and expiry are handled.
Test backup and restore for the system, not one shard. A collection of independently restorable databases may represent different logical times. Recovery objectives determine whether coordinated snapshots, transaction logs, or application-level reconciliation are necessary.
Make the least distributed choice that solves the problem
Use PostgreSQL partitioning when table organization, pruning, or lifecycle maintenance aligns with a clear partition key and one database remains an acceptable resource and failure boundary. Use sharding when measured storage or workload constraints genuinely require multiple ownership nodes and the domain can support routing and coordination tradeoffs.
A performance and reliability assessment can distinguish query, indexing, maintenance, capacity, and topology problems before a permanent distribution decision. The most effective design is often the least distributed one that satisfies the measured requirement—and the one whose recovery and migration procedures the team can actually operate.